

A language learner may know the words but still need a comfortable place to practice speaking. A voice practice partner can start a conversation, listen to the learner's answers, and keep the exchange moving without the pressure of speaking with another person.
With the Zoom Voice Agent, you can build that experience as a real-time spoken conversation. For example, an English learner can practice ordering at a cafe: the agent plays the barista, asks follow-up questions, and responds naturally when the learner pauses, changes their answer, or asks for help. In parallel, your application can use the conversation transcript to offer feedback on vocabulary and phrasing after each turn.
Why use Zoom for speaking practice
The Voice Agent API handles the real-time conversation loop over a WebSocket connection. Your app streams microphone audio and receives spoken responses, transcripts, and events as the conversation progresses. This gives the learner more control over their learning experience, customizing it to their needs.
Learners can speak at their own pace. Automatic turn detection determines when an utterance is complete, and barge-in lets them interrupt the agent to ask a question or try again. Your app can also use function calls to manage practice activities, such as switching scenarios or tracking completed exercises.
What you can build
| Capability | What it enables |
|---|---|
| Turn detection | Server VAD or semantic VAD detects when the learner finishes speaking. |
| Streaming audio | Stream Base64 PCM16, G.711 µ-law, or G.711 A-law input; receive PCM16 audio at 16 kHz. |
| Server events | Receive speech, transcript, response, and function-call events as they happen. |
| Barge-in | Let learners interrupt an agent response and speak naturally. |
| Function calling | Connect the agent to app functions, such as choosing the next practice scenario. |
Get started
You'll run the quickstart app locally, connect to the Voice Agent, and use the playground to practice a spoken conversation.
Prerequisites
- A Zoom developer account on the Build platform
- For batch: IAM credentials to access an S3 bucket
- Node v24+
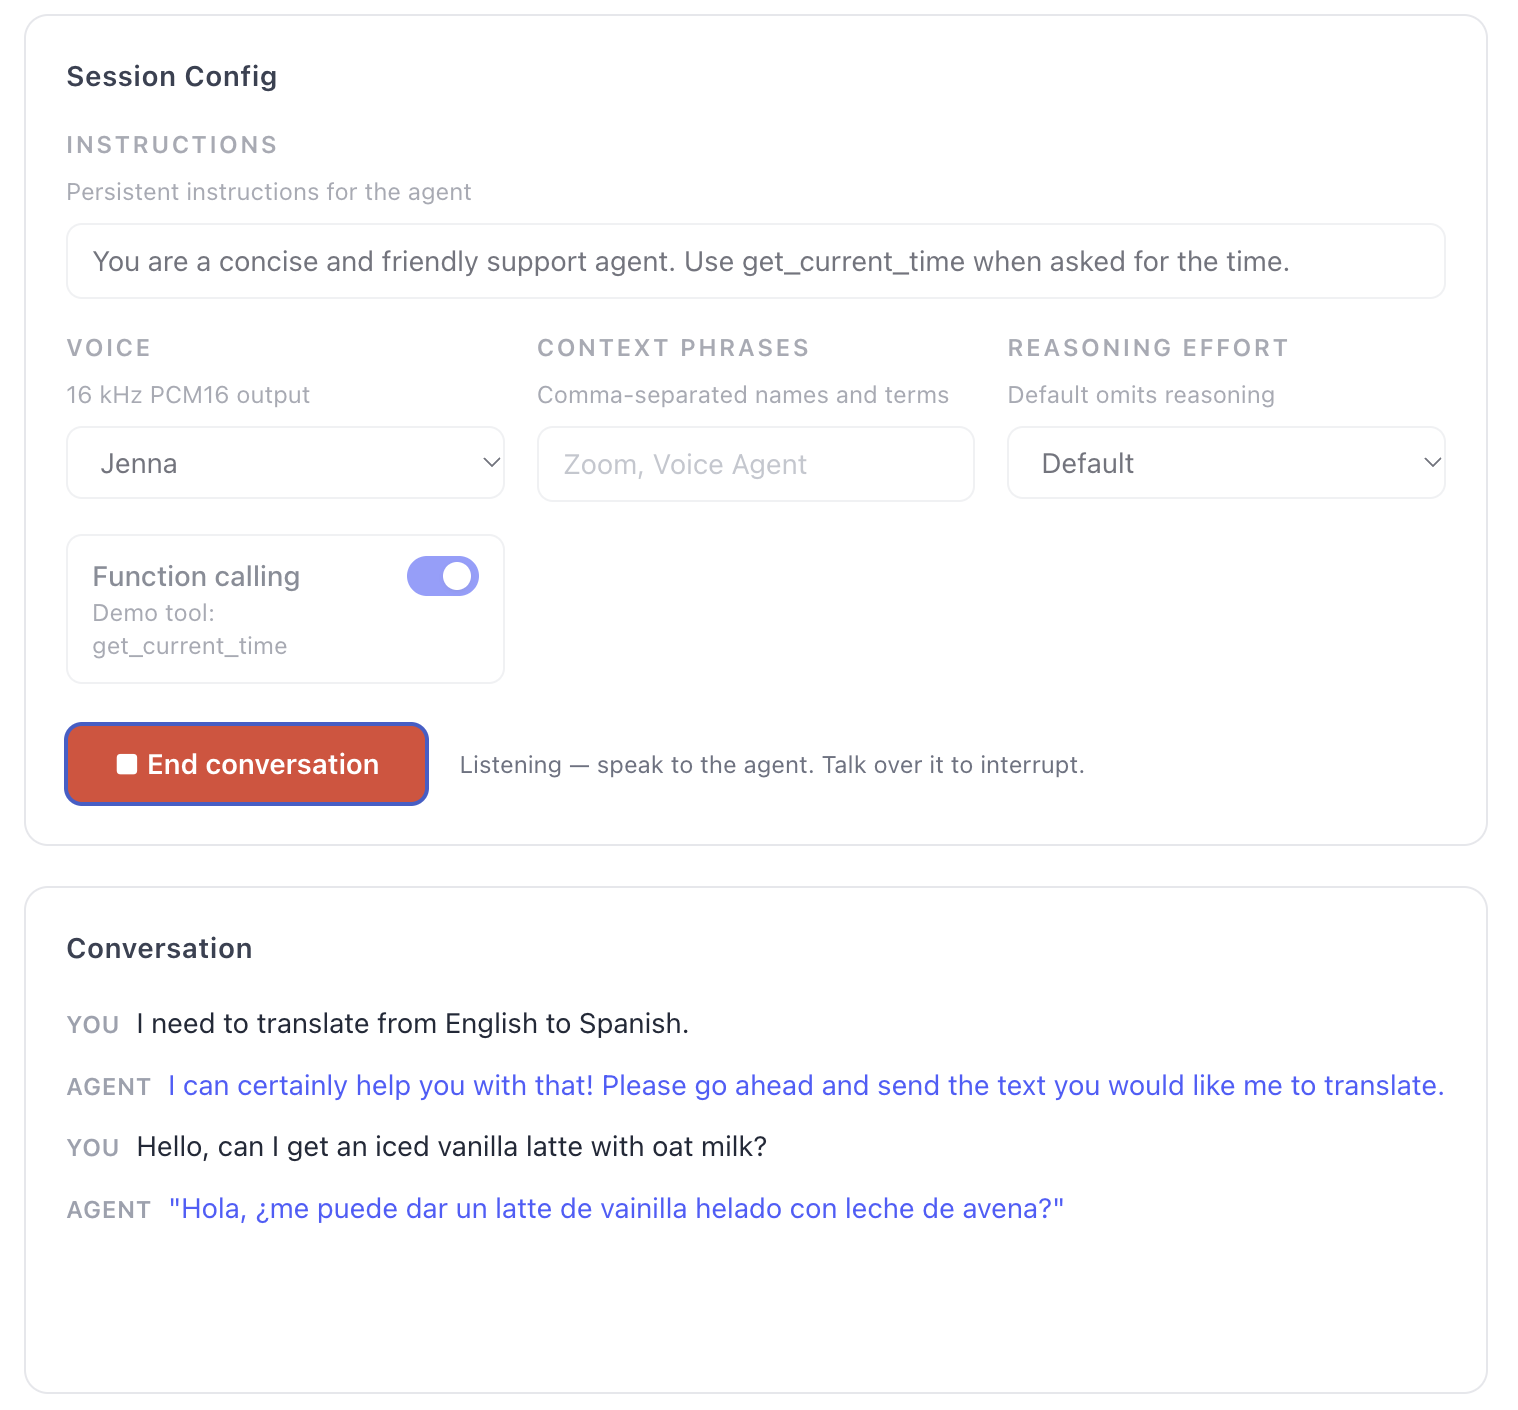
Open the AI Services Playground to select Voice Agent and try a speaking-practice scenario.
Voice Agent setup
The quickstart app has the browser connect to a small Node relay, which opens the Zoom WebSocket and adds your JWT. Browsers can't set an Authorization header on a WebSocket, so the relay does it for you.
Connect over WebSocket
The relay in src/live/relay.ts connects to the Voice Agent endpoint with the voice-agent.zoom.v2 subprotocol:
const upstream = new WebSocket(
    `${WSS_ROOT}/ws/aiservices/voice-agent/live`,
    ['voice-agent.zoom.v2'],
    { headers: { Authorization: `Bearer ${generateJWT()}` } },
);
The browser then connects to the relay:
const ws = new WebSocket(`ws://${location.host}/live/voice-agent`);
Events
On a high level, the communication with the language coach happens through these series of events:
| Direction | Event | Purpose |
|---|---|---|
| Receive | session.created | Connection is ready for configuration. |
| Send | session.update | Configure the agent. This must be the first client event. |
| Receive | session.updated | Configuration accepted; start streaming audio. |
| Send | input_audio_buffer.append | Base64 audio chunk from the microphone. |
| Receive | input_audio_buffer.speech_started | The learner started speaking (barge-in). |
| Receive | conversation.item.input_audio_transcription.completed | Final transcript of the learner's turn. |
| Receive | response.output_audio_transcript.delta | Streaming text of the agent's reply. |
| Receive | response.output_audio.delta | Base64 PCM16 audio of the agent's reply. |
| Receive | error | Validation errors are nonfatal; the session stays open. |
Configure the agent
When session.created arrives, send session.update. The listen block describes the audio you send, think is the LLM and its role, and speak is the voice you get back. Server events arrive wrapped in a payload object.
ws.onmessage = (msg) => {
    const envelope = JSON.parse(msg.data);
    const event = envelope.payload ?? envelope;

    if (event.type === 'session.created') {
        ws.send(
            JSON.stringify({
                type: 'session.update',
                session: {
                    type: 'realtime',
                    listen: {
                        format: { type: 'pcm16', rate: 16000 },
                        transcription: { language: 'en' },
                    },
                    think: {
                        provider: { type: 'zoom', model: 'gemma-4' },
                        instructions:
                            'You are a friendly barista. Keep replies short and ask follow-up questions.',
                    },
                    speak: { format: { type: 'pcm16' }, voice },
                },
            }),
        );
    }
    if (event.type === 'session.updated') configured = true;
};
Record and stream microphone audio
The agent expects Base64 PCM16 audio. Create the AudioContext at 16 kHz so the browser resamples the microphone for you, then use an AudioWorklet to convert Float32 samples to 16-bit PCM in 100 ms chunks.
const stream = await navigator.mediaDevices.getUserMedia({
    audio: { channelCount: 1, echoCancellation: true, noiseSuppression: true },
});
const ctx = new AudioContext({ sampleRate: 16000 });
await ctx.audioWorklet.addModule('/pcm-worklet.js');

const node = new AudioWorkletNode(ctx, 'pcm-processor');
ctx.createMediaStreamSource(stream).connect(node);

node.port.onmessage = (e) => {
    if (configured && ws.readyState === WebSocket.OPEN) {
        ws.send(
            JSON.stringify({
                type: 'input_audio_buffer.append',
                audio: toBase64(e.data),
            }),
        );
    }
};
Send audio only after session.updated. Turn detection runs on the server, so you never need to commit the buffer.
Receive the response and transcript
Handle the server events in the same onmessage switch.
Transcripts. The learner's turn arrives once as a completed transcript. The agent's reply streams as deltas that you append to a single line.
case 'conversation.item.input_audio_transcription.completed':
  addLine({ role: 'user', text: event.transcript })
  break
case 'response.output_audio_transcript.delta':
  appendToAgentLine(event.response_id, event.delta)
  break
Audio. Each response.output_audio.delta is a Base64 PCM16 chunk at 16 kHz. Decode it to Float32 and schedule it right after the previous chunk so playback is gapless.
function pcm16ToFloat32(base64: string) {
    const bytes = Uint8Array.from(atob(base64), (c) => c.charCodeAt(0));
    const pcm = new Int16Array(bytes.buffer, 0, bytes.length >> 1);
    return Float32Array.from(pcm, (s) => s / 0x8000);
}

function play(base64: string) {
    const samples = pcm16ToFloat32(base64);
    const buffer = ctx.createBuffer(1, samples.length, 16000);
    buffer.copyToChannel(samples, 0);

    const source = ctx.createBufferSource();
    source.buffer = buffer;
    source.connect(ctx.destination);

    const at = Math.max(ctx.currentTime, playhead);
    source.start(at);
    playhead = at + buffer.duration;
    playing.push(source);
}
Barge-in. When the learner speaks over the agent, stop the queued audio:
case 'input_audio_buffer.speech_started':
  playing.forEach(s => s.stop())
  playing = []
  playhead = 0
  break
See useVoiceAgent.ts for the complete hook, including function calling.
Next steps
- Clone the quickstart app and try a speaking-practice scenario with the Voice Agent.
- Open the AI Services Playground to experiment with a different role, prompt, or turn-taking style.
- Read the Voice Agent docs for session configuration, audio streaming, server events, and function calling.