

Few things frustrate a customer more than explaining the same problem twice. When a support case moves from tier 1 to tier 2, the customer often repeats what they've already tried, and the engineer spends the first few minutes catching up instead of fixing the issue.
With the Zoom Speech Summarizer, you can hand the next agent a recap before they say hello. Send the call recording to the API and it transcribes the audio, then streams back a summary as it's generated. For example, while a tier 1 agent is still wrapping up, your app can show the escalation engineer the symptoms, the steps already tried, and the open questions, each linked back to who said it and when.
Why use Zoom for escalation recaps
The Speech Summarizer takes an audio or video file and returns the transcript and summary over a single streaming connection. You don't need to run a separate transcription step or wait for the whole job to finish: summary updates arrive as Server-Sent Events (SSE), so your app can render the recap as it's written.
Summaries follow a template, so the output matches the way your team works. Use a built-in template like customer_success, write your own, or let the API detect the conversation type automatically. Citations tie each point back to a speaker and timestamp, so an engineer can verify a detail without replaying the call.
What you can build
| Capability | What it enables |
|---|---|
| Audio and video input | Upload WAV, MP3, M4A, WebM, or MP4 files up to 50 MB and 2 hours. |
| Streaming summaries | Receive summary updates over SSE while the summary is being generated. |
| Templates | Choose a built-in template, supply a custom one, or detect the type automatically. |
| Citations | Link each summary point to the speaker and time range it came from. |
| Diarization | Label who said what in the transcript. |
| Language control | Set the spoken language and write the summary in a different one. |
Get started
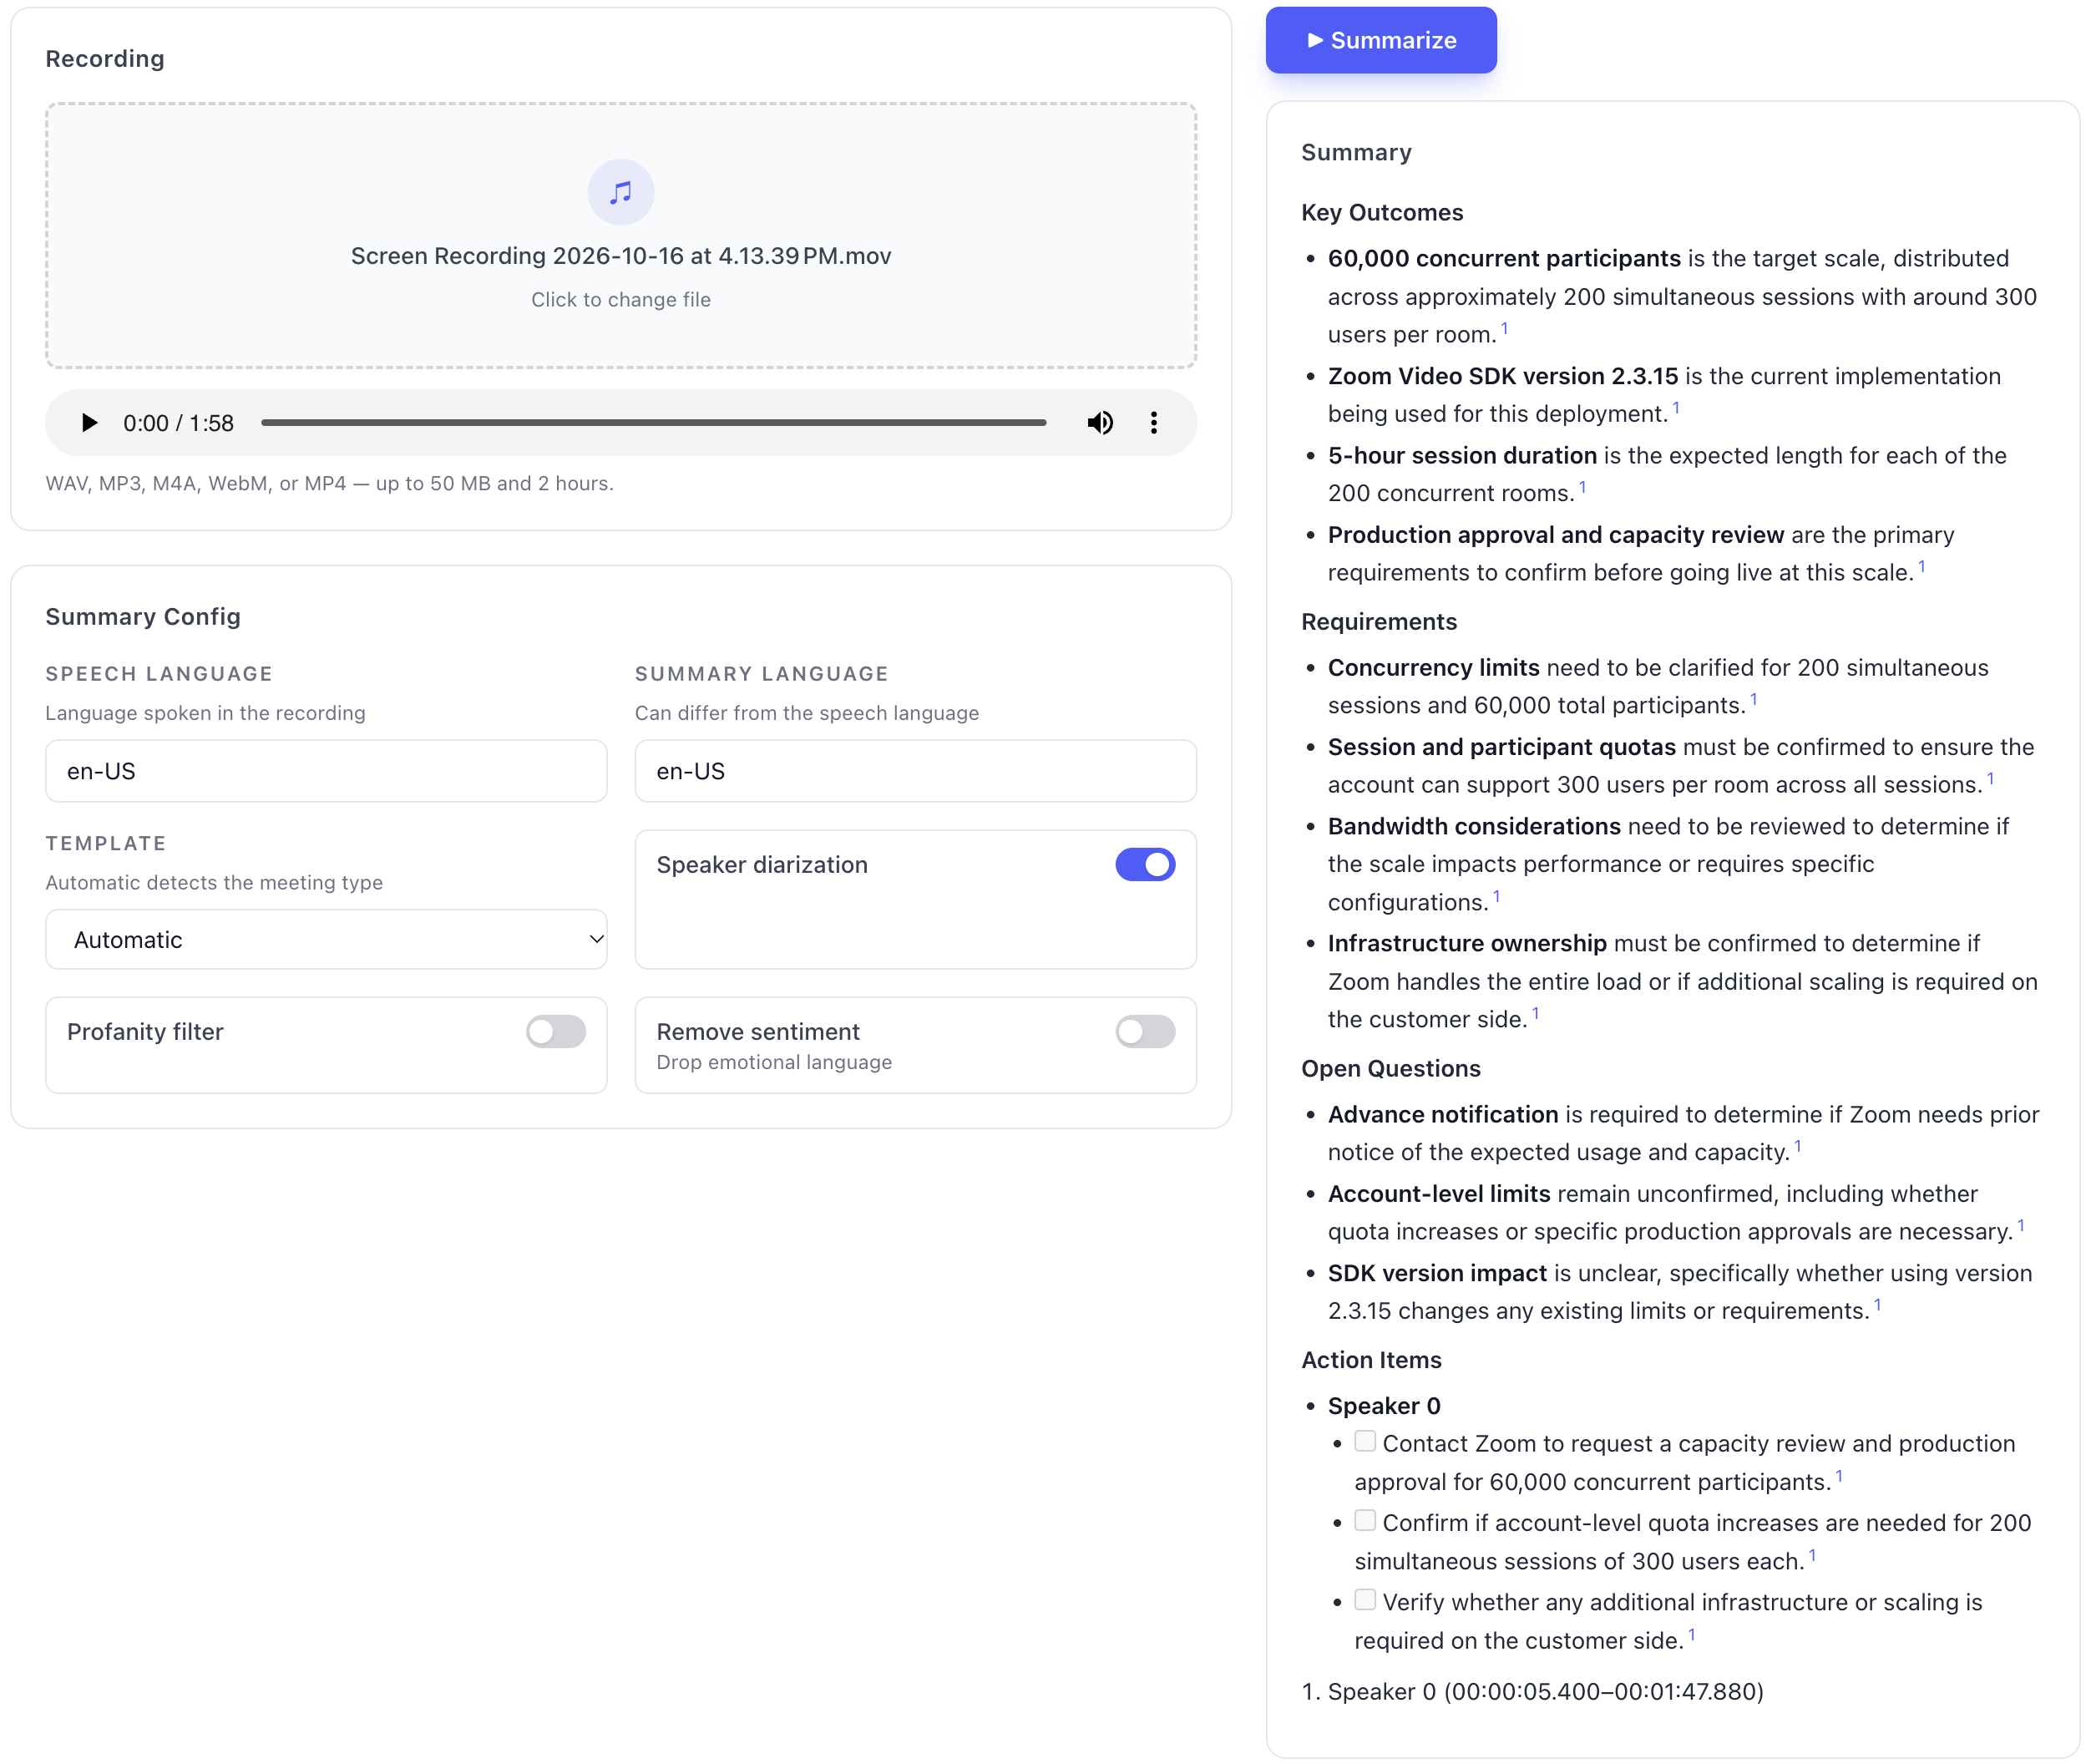
You can run the AI Services Playground locally, select Speech Summarization, and try it with your own recording. Simply upload a support call recording, and watch the escalation recap stream in.
Prerequisites
- A Zoom developer account on the Build platform
- Node v24+
- A sample call recording (audio or video) of a troubleshooting conversation
Speech Summarizer setup
The playground app uploads the file to a small Node backend, which forwards it to Zoom with your JWT and pipes the SSE response straight back to the browser. This keeps your credentials off the client.
Send the file to the API
The backend handler in src/routers/speechSummarization.ts accepts a multipart upload, adds the config, and requests an event stream:
const form = new FormData();
form.append(
    'file',
    new Blob([req.file.buffer], { type: req.file.mimetype }),
    req.file.originalname,
);
if (typeof req.body.config === 'string') form.append('config', req.body.config);

//zoomFetch makes request to https://api.zoom.us/v2/speech-summarization/summarize
const upstream = await zoomFetch('/speech-summarization/summarize', {
    method: 'POST',
    headers: { Accept: 'text/event-stream' },
    body: form,
});

res.status(upstream.status);
res.setHeader(
    'Content-Type',
    upstream.headers.get('content-type') ?? 'text/event-stream',
);
Readable.fromWeb(upstream.body).pipe(res);
Configure the summary
The config field has two parts: transcribe controls how the audio is converted to text, and summary controls how the recap is written. This is the configuration for an escalation recap:
const config = {
    transcribe: {
        language: 'en-US',
        diarization: true, // label the customer and the agent
        profanity_filter: false,
    },
    summary: {
        language: 'en-US',
        citations: true, // link points to speaker and time
        should_remove_sentiment: false,
        template_id: 'customer_success',
        enable_dynamic_template: false,
    },
};

const form = new FormData();
form.append('file', file);
form.append('config', JSON.stringify(config));
Pick the template that shapes the recap:
| Option | Config |
|---|---|
| Built-in template | template_id: 'customer_success' with enable_dynamic_template: false |
| Your own structure | custom_template: '...' with enable_dynamic_template: false |
| Automatic | enable_dynamic_template: true |
For example, a custom template can ask for exactly what an escalation engineer needs: the reported issue, steps already tried, and what the customer expects next.
The same request to the API with curl looks like this. --no-buffer prints the SSE events as they arrive:
curl --no-buffer -X POST "https://api.zoom.us/v2/speech-summarization/summarize" \
  -H "Authorization: Bearer $ZOOM_JWT" \
  -H "Accept: text/event-stream" \
  -F "file=@escalation-call.mp4" \
  -F 'config={
    "transcribe": { "language": "en-US", "diarization": true, "profanity_filter": false },
    "summary": {
      "language": "en-US",
      "citations": true,
      "should_remove_sentiment": false,
      "template_id": "customer_success",
      "enable_dynamic_template": false
    }
  }'
Run it and retrieve the summary
Post the form to the backend, then read the response as a stream. SSE events are separated by blank lines, so buffer the text and parse only complete events.
const res = await fetch('/api/speech-summarization', {
    method: 'POST',
    body: form,
});
const reader = res.body.pipeThrough(new TextDecoderStream()).getReader();

let buffer = '';
for (;;) {
    const { value, done } = await reader.read();
    if (done) break;
    const [events, rest] = parseSse(buffer + value);
    buffer = rest; // keep the unfinished event for the next chunk
    events.forEach(handleEvent);
}
parseSse splits the buffer into event and data pairs:
function parseSse(buffer: string): [StreamEvent[], string] {
    const blocks = buffer.split(/\r?\n\r?\n/);
    const rest = blocks.pop() ?? '';
    const events = blocks.filter(Boolean).map((block) => {
        const lines = block.split(/\r?\n/);
        const event =
            lines
                .find((l) => l.startsWith('event:'))
                ?.slice(6)
                .trim() ?? 'message';
        const data = lines
            .filter((l) => l.startsWith('data:'))
            .map((l) => l.slice(5).trimStart())
            .join('\n');
        return { event, data };
    });
    return [events, rest];
}
Handle the events
Handle each event as it arrives. The transcript lands once when transcription finishes, and every summary update carries the full summary so far, so replace the text instead of appending.
const handleEvent = ({ event, data }: StreamEvent) => {
    const json = JSON.parse(data);

    if (Array.isArray(json.citations)) setCitations(json.citations);

    if (event === 'transcribe_complete') {
        setTranscript(json.transcript?.result?.text_display ?? '');
    } else if (event === 'error') {
        setError(String(json.error ?? data));
    } else if (typeof json.summary === 'string') {
        setSummary(json.summary); // replace, don't append
    } else if (typeof json.summary_result === 'string') {
        setSummary(json.summary_result); // final summary
    }
};
The result is a recap an escalation engineer can scan in seconds, such as "Customer reports intermittent sync failures after the 5.2 update[^1]", with a link back to the moment it was said. See SummarizeTab.tsx for the complete component.
Next steps
- Clone the quickstart app and summarize a support call with the Speech Summarizer.
- Open the AI Services Playground to experiment with templates, languages, and citations.
- Read the Speech Summarizer docs for configuration options, supported formats, and event details.